Blog
The Curse of Unbounded Contexts, Chelsea Troy on Using Domains as LLM Consumers
Posted on 2026-10-05 - 4 minute read
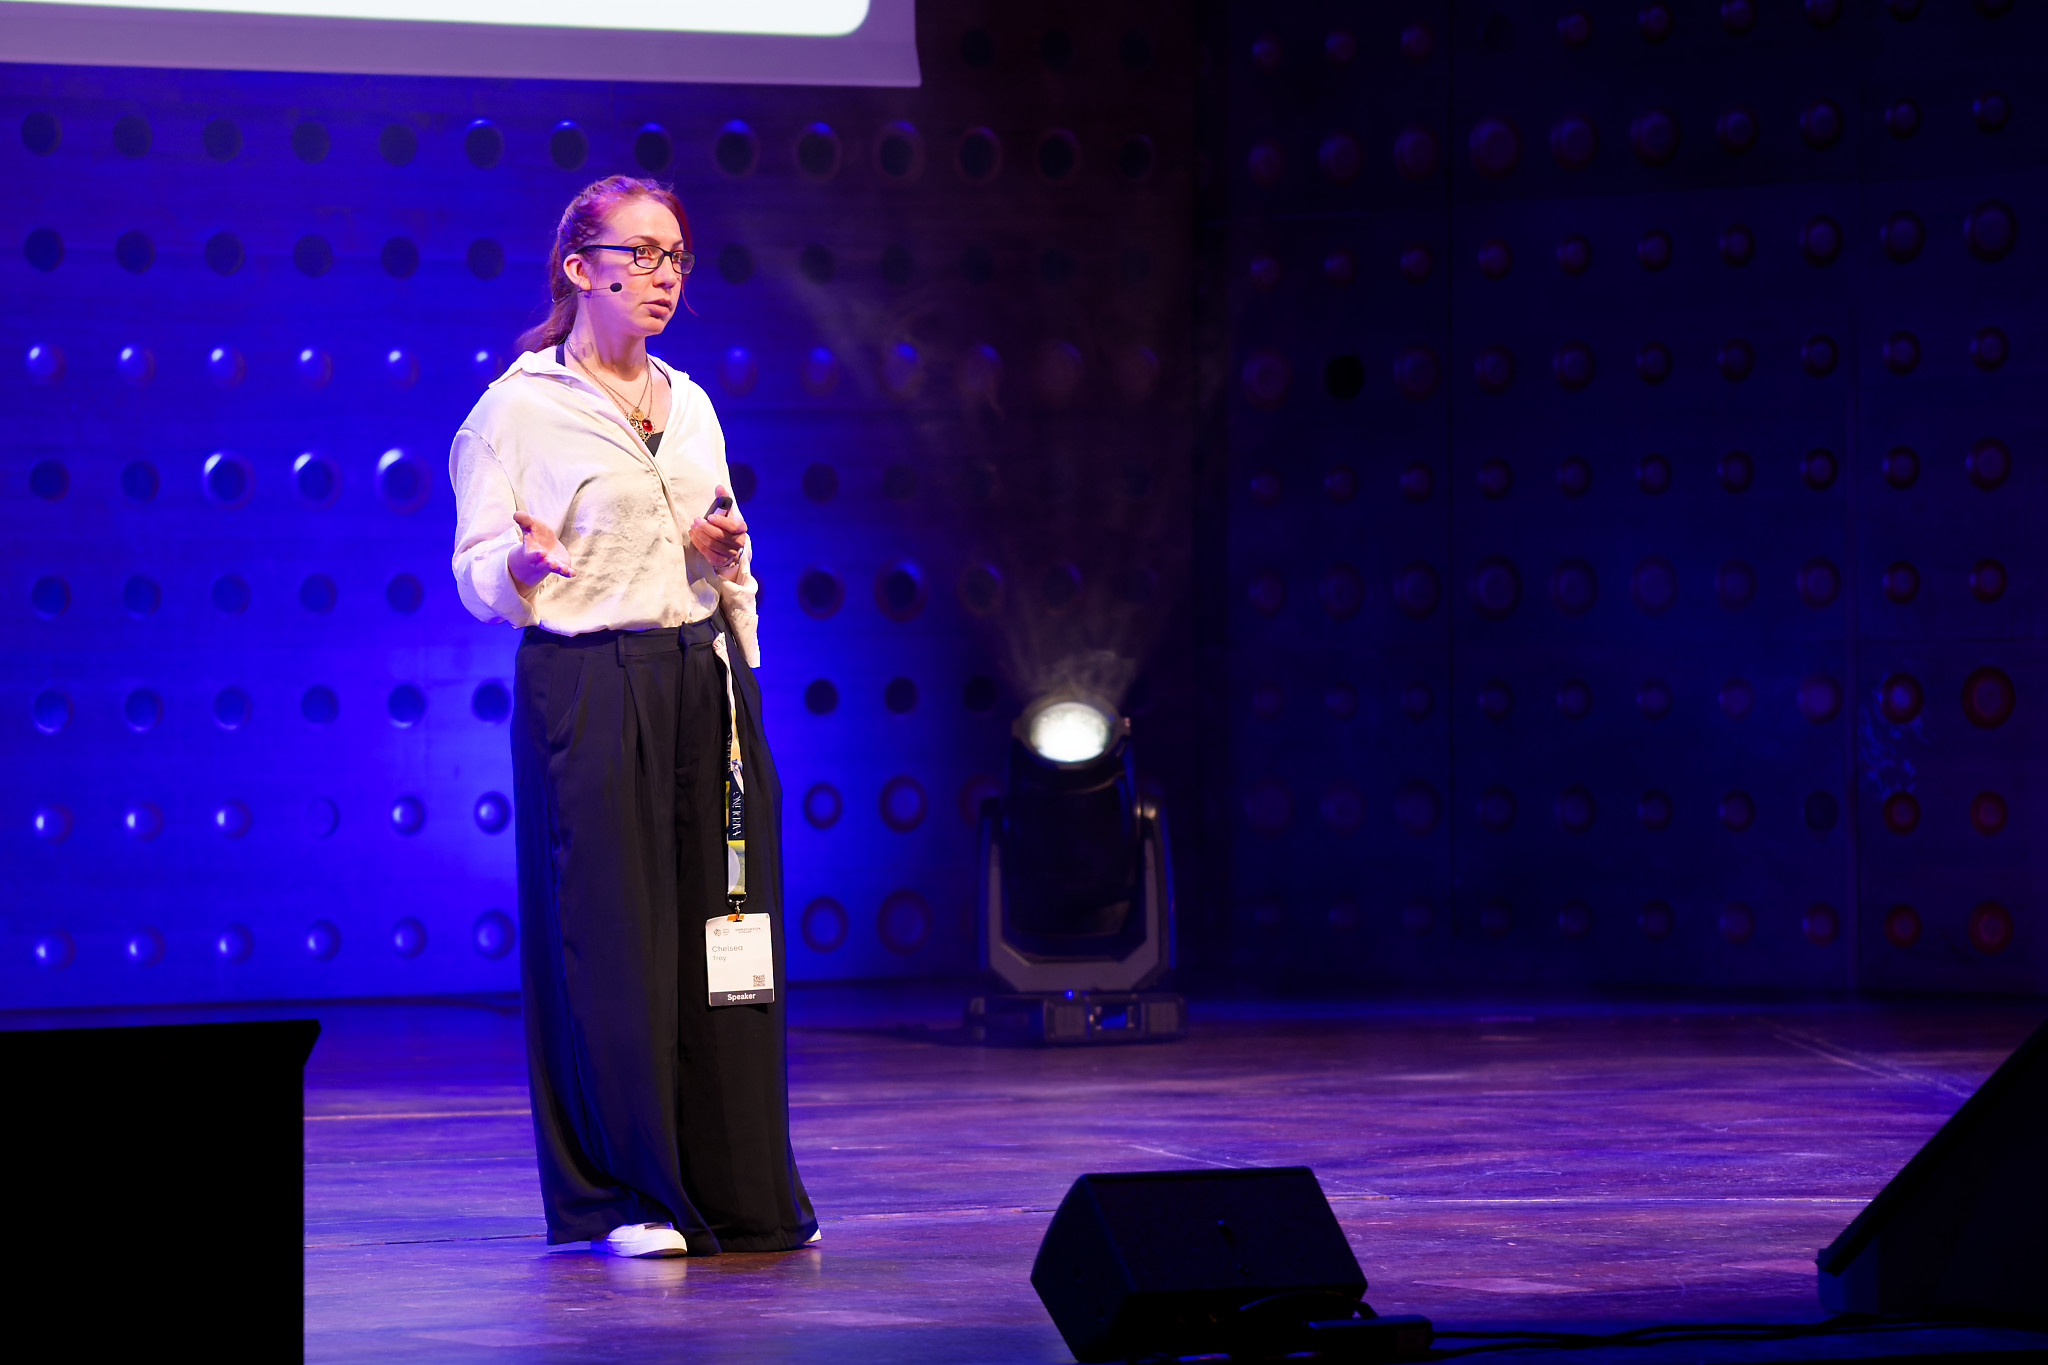
Chelsea Troy, who leads Mozilla's machine learning operations team and teaches computer science at the University of Chicago, spends her days watching two very different groups struggle with the same problem: early-career master's students and seasoned professional engineers, both trying to get useful work out of LLM coding tools. Her DDD Europe talk, "The Curse of Unbounded Contexts: Using Domains as LLM Consumers," argues that Domain-Driven Design already gave us the vocabulary to fix this, we've just not been applying it to our conversations with AI.
The problem is bounded context, not the model
Troy opens with two familiar scenarios. In the first, she asks her tool to "optimise the model," meaning her machine learning pipeline, and the LLM confidently starts editing a Django ORM model instead. The mismatch is caught quickly because the tool's response reveals the misunderstanding. In the second, subtler case, she tells her tool never to use exceptions for control flow, the tool agrees, and dozens of messages later it quietly reintroduces a try/except block anyway. Nothing was forgotten. The instruction is still in the context window, just diluted by everything said since.
Both problems, she argues, are bounded context violations: the assumption that a word, or an instruction, means the same thing throughout a conversation when nothing has actually enforced that.
Four failure modes, and what to do about each
Troy walks through four specific ways this breaks down in practice:
- Language mismatch at the start, where you and the tool silently disagree on what a term means from message one.
- Context degrading its own signal, where an early instruction loses relative weight as a long conversation accumulates unrelated content.
- One context, multiple domains, where a single conversation drifts from exploration to brainstorming to implementation without ever resetting.
- Failure to separate vocabularies cleanly, the point where correcting the tool stops working and the context needs replacing outright, not patching.
For each, she offers a genuinely practical fix rather than a vague principle: a terminology block stated before the first question, reanchoring constraints every 15 to 20 messages, naming which of four conversational "registers" (exploring, brainstorming, deciding, implementing) you're actually in, and a third-time rule, if you've corrected the same thing three times without it sticking, stop correcting and start a new conversation instead.
Why this matters for teams already doing DDD
The talk's sharpest insight might be the reframe at the end: the same context discipline that makes LLM tools reliable is discipline. Most engineers already practise discipline when collaborating with other humans. A conversation charter, in Troy's framing, is just a bounded context applied to a chat window. The anti-corruption layer, a familiar DDD pattern for isolating vocabularies between systems, applies just as directly to isolating vocabularies between conversations with an AI tool.
Her closing point is one every DDD practitioner will recognise instinctively: ambiguity isn't the enemy, unacknowledged ambiguity is. The fix was never about writing a cleverer prompt. It's about doing the same boundary-drawing work we already know how to do.
This is what participants said:
Great presentation: both form and content were top notch. I learned a lot about prompting. This talk will improve my use of LLMs.
I really enjoyed the systematic explanation of the process and all the knowledge on it. The impact of this talk will be quite fast, since I will rethink the way I use LLMs. Even if I was already doing some of it intuitively, but not consciously. I will share this with my team.
Great presentation. The topic is super relevant and the way the presenter used DDD concepts was very good. It gave me some ideas on how to refine some of my workflows.
Watch the full talk for the live examples, including the four-register framework and the 2x2 matrix for predicting when LLM tools are likely to succeed versus when they need real structure.